Building Agents? Stop Treating messages[] Like a Database
Stop using messages as your agent's memory. Learn how structured state makes AI agents more reliable, efficient, and production-ready.
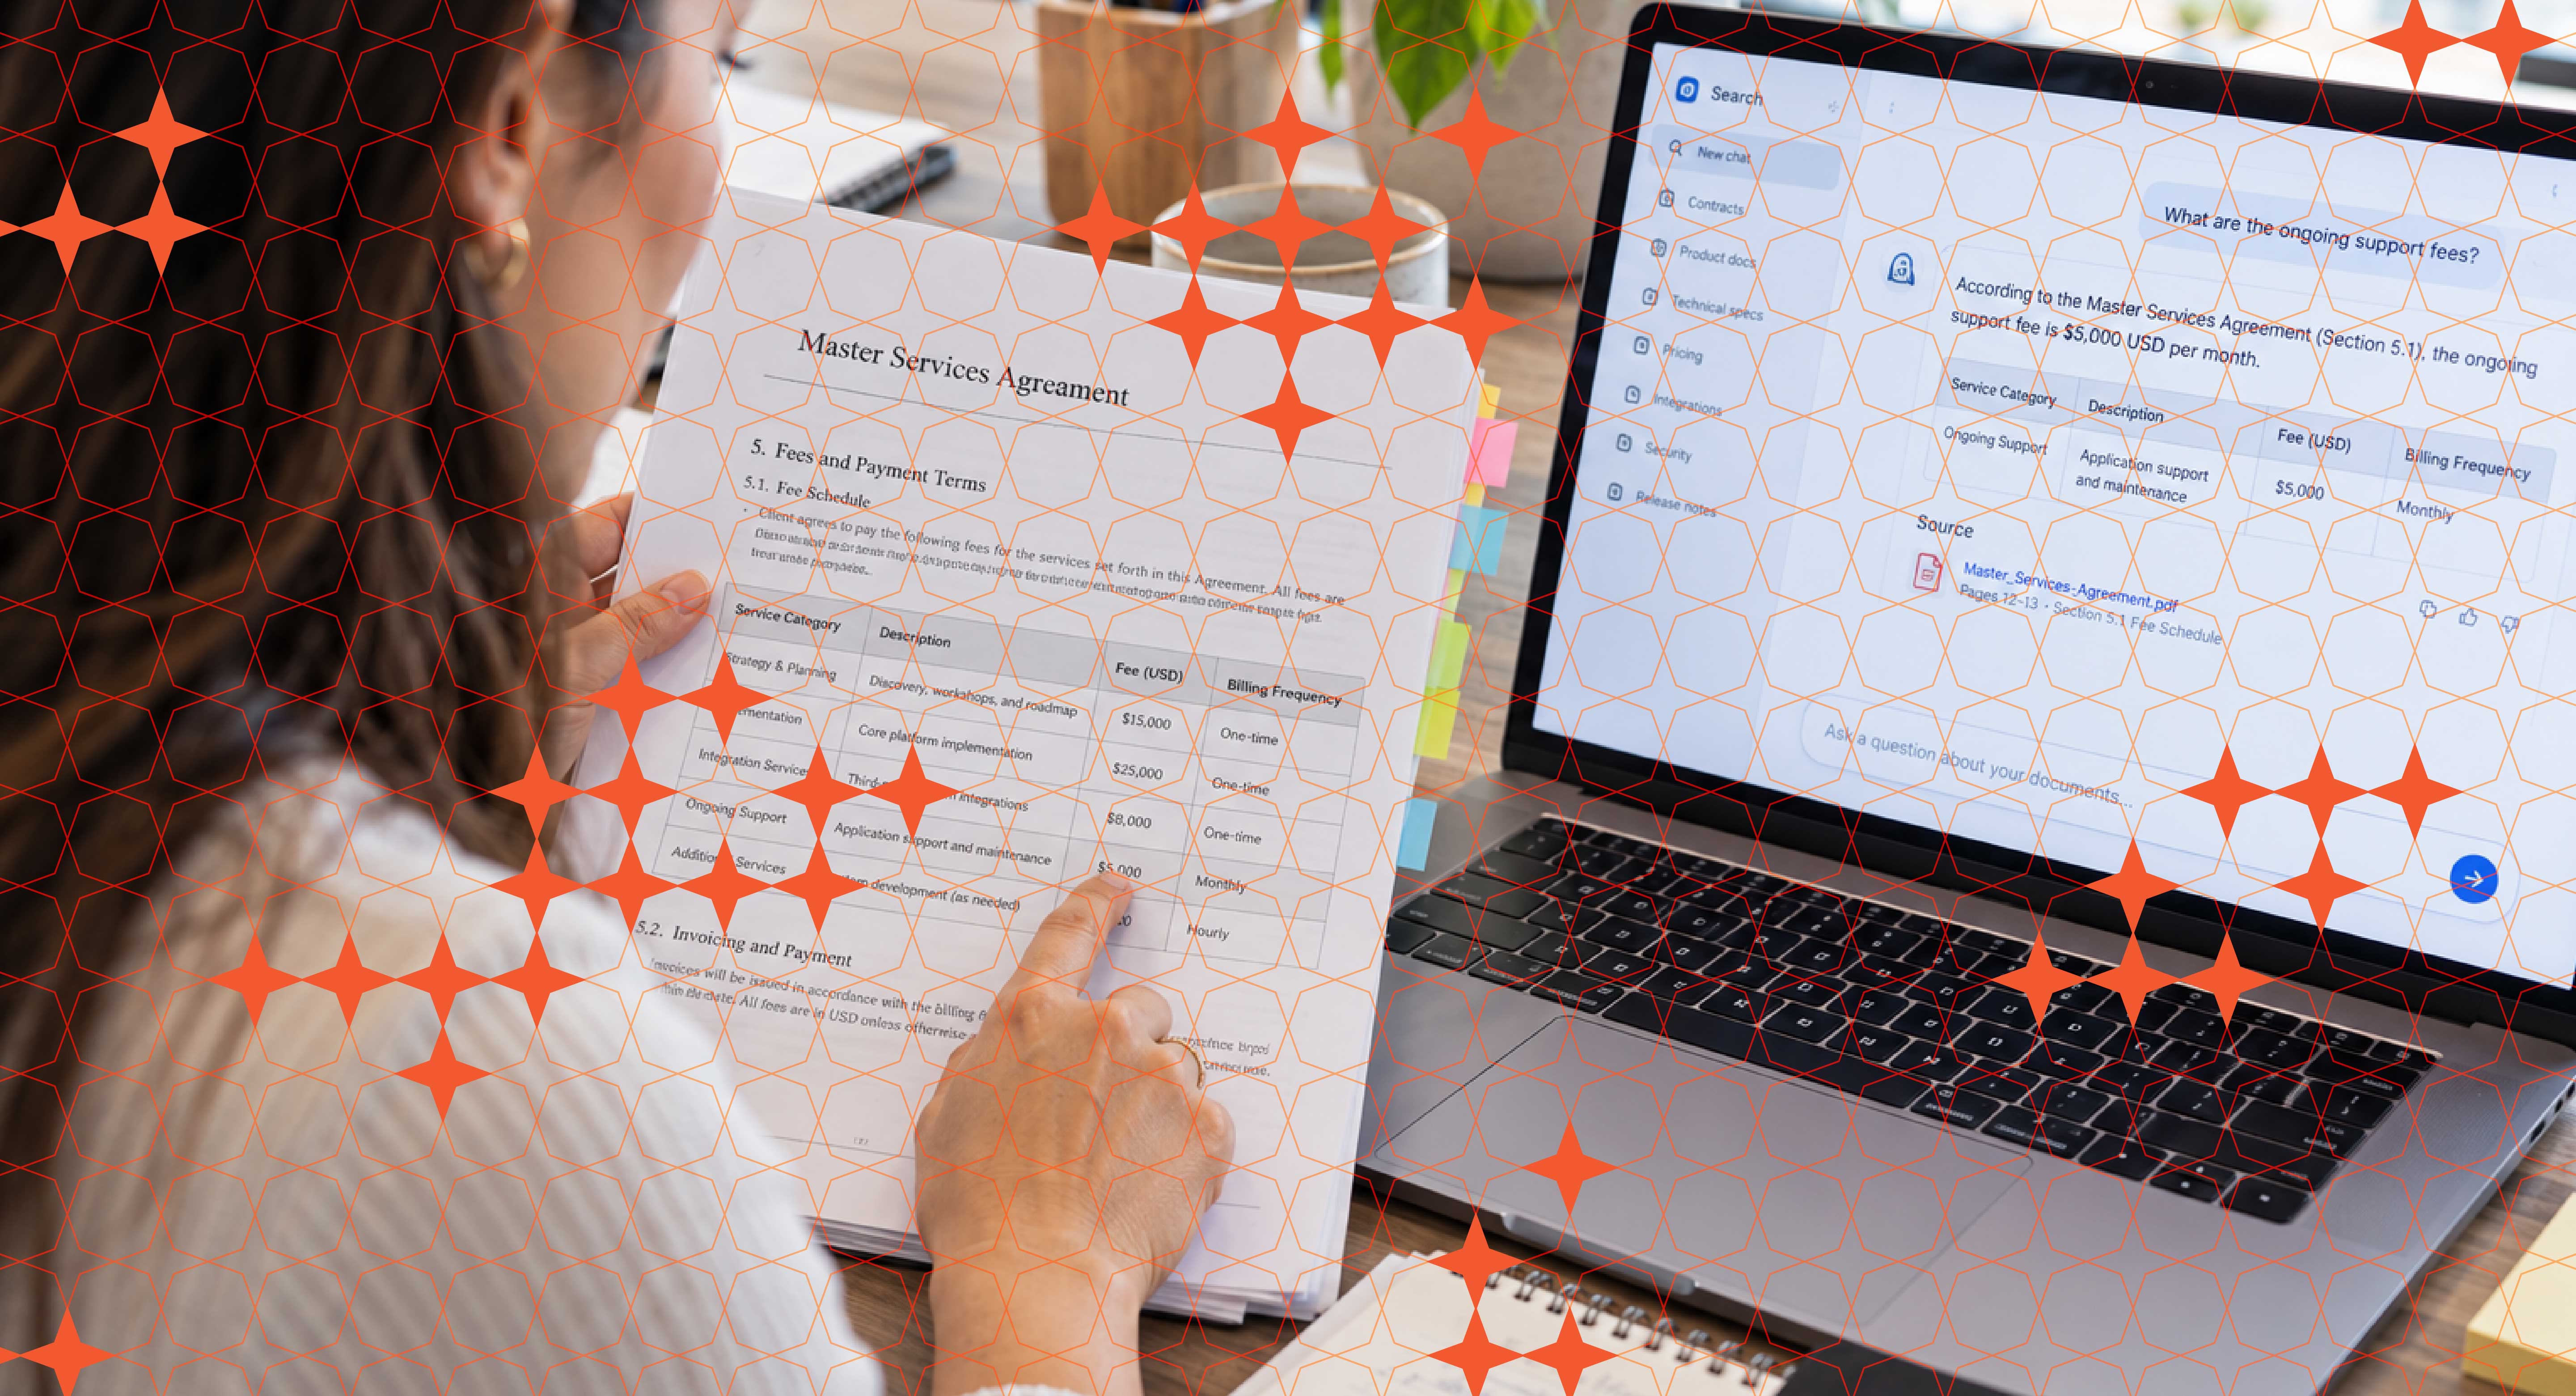
If you own the digital product, AI search arrives on your roadmap with a practical question attached: Where should the next dollar be invested?
At Pureinsights, I help enterprises take AI search from pilot to production, and the answer starts with how these systems are built. AI search works in four layers:
Each of the first three sets a ceiling for the next. Content limits what search can find, and search limits what the answer can say. Getting one layer right while neglecting the others produces a system that may never reach production, so the order you invest in matters.
What follows is the key decision we make at each layer, drawn from our ebook, Making AI Search Work, which covers each one in more depth.
Most implementations start by cutting every document into equal-sized pieces, ignoring headings and layout. The result is meaning gets lost at the cuts: a table row lands in one piece and its caption in another, or a clause that says "see Article 7" is stored with no trace of what Article 7 says. Splitting content along its own structure keeps those pieces whole. (That means you need to keep tables, too. They often hold the most precise answers, such as fee schedules and specification values, and customers in a chat interface may never open the original document to find them.)
Semantic search, which matches on meaning rather than exact words, handles most questions well enough. The failures are in the remainder: requests for the exact wording of a policy clause, lookups by part number or SKU and questions about the current version of a document when older drafts are still indexed. In each case, semantic search returns something close rather than something exact, and one or two confidently wrong answers are enough to shake users’ confidence.
The primary way to account for this is to classify each question first, then send it to a specialist. Citations go to exact-text search, and anything time-sensitive goes to a search that knows which version is current. Across our deployments, no other change has improved accuracy as much. The classification takes milliseconds, and it lowers cost because expensive methods only run when a question needs them.
Ranking is the other half of the solution. Outdated or unofficial content is consistently the top trust issue we see. Weighting results by source type and validity dates keeps current, official documents on top, and returning the exact source passage with each answer lets users check it for themselves.
Out of the box, generated answers aren't conservative enough where liability is involved. Most of the fix is in the instructions: answer only from the retrieved passages, cite them and be explicit about saying when they don't cover the question.
Multi-part questions need their own handling. "Can I return a sale item I bought online to a store in another country?" bundles several policies into one sentence, and a single search returns an answer that covers only part of it, with nothing to tell the customer what's missing. These questions are typically the largest gap between test accuracy and real-world accuracy. Splitting them into parts before searching is what closes that gap.
At scale, response time becomes the constraint, and where each step runs matters. Every query that calls an external AI service adds a round trip, and that service's response time is outside your control.
One engagement can show the size of the effect: A client had a target of 95 percent of responses in under 400 milliseconds at 65 queries per second, but their 95th-percentile response time was tracking above 600 milliseconds. To solve that issue, we moved the step that converts each question into a searchable form from an external service to an open-source equivalent running in AWS SageMaker, alongside the search platform. The result? At the same traffic, 95 percent of responses came back in just 144 milliseconds.
One final note: cost optimizations, such as compressing that searchable form, give up some precision. Before anyone optimizes, build a golden query set: a fixed list of real questions with known good answers, and test every change against it.
Getting this right isn’t about solving everything today. It’s about building the foundation, step by step, to create the outcomes you need. Ask one question per layer, in order:
If the answer to the first is no, that's where the next dollar goes.
This post covers one decision per layer. The ebook goes further, with the six changes that had the broadest impact across our deployments, how to turn requests like "last year's sales decks" into precise search filters, when a knowledge graph is worth adding and how one client freed an entire search cluster by consolidating duplicate indexes.
Matt Willsmore is a Principal Architect at Pureinsights, where he helps enterprises take AI search and RAG from pilot to production. Read his full technical dive on this topic or you can download the full e-book, Making AI Search Work: Lessons from the Field on RAG in Production.
Stop using messages as your agent's memory. Learn how structured state makes AI agents more reliable, efficient, and production-ready.

Traditional approaches to change management weren’t working before. AI just makes the gaps impossible to ignore.

How smart companies are evolving with agent-powered delivery models, and what it takes to lead in the new era of intelligent services.